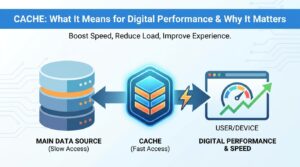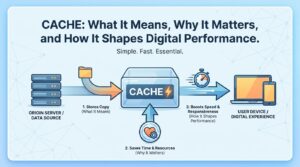
Caching, one of the most fundamental mechanisms in modern computing, underpins everything from how quickly a webpage loads to how efficiently a database serves millions of concurrent queries. Yet for all its ubiquity, the concept remains poorly understood outside engineering circles. At its core, a cache stores copies of frequently accessed data in a faster-access layer, reducing the need to repeatedly fetch information from slower origins. The business implications of getting caching right (or wrong) ripple across user experience, infrastructure costs, and competitive positioning.
Why Caching Deserves Executive Attention
Most conversations about cache happen in server rooms or Slack channels between backend engineers. But the strategic weight of caching decisions extends well beyond technical architecture. Before diving deeper, here are the key points worth internalizing:
- Effective caching can reduce server response times by 80% or more, directly improving customer-facing performance metrics
- Poorly configured cache layers introduce stale data risks, which in regulated industries can carry compliance consequences
- Cloud infrastructure spend is tightly coupled to cache hit ratios; even marginal improvements translate into measurable cost savings at scale
- Content delivery networks rely almost entirely on distributed caching to serve global audiences, making cache strategy inseparable from international expansion
- Browser-level caching policies affect SEO rankings, as page speed remains a confirmed signal in search algorithms
How Caching Actually Works
The principle is deceptively simple. When a system retrieves data from a primary source, whether a database, an API, or a filesystem, it stores a copy in a faster medium. Subsequent requests for the same data hit the cache instead of the origin. That’s the theory.
In practice, caching introduces a set of tradeoffs that require careful calibration. How long should cached data persist before it’s considered stale? What happens when the underlying data changes? Which data deserves cache space, and which doesn’t? These questions don’t have universal answers. They depend on the application, the user base, and the tolerance for serving slightly outdated information.
There are several distinct layers where caching operates:
| Cache Layer | Location | Typical Use Case | Invalidation Complexity |
|---|---|---|---|
| Browser Cache | End-user device | Static assets like images, CSS, JavaScript | Low — controlled via HTTP headers |
| CDN Cache | Edge servers globally distributed | Web pages, media files, API responses | Moderate — purge mechanisms vary by provider |
| Application Cache | Server memory (e.g., Redis, Memcached) | Session data, computed results, database query results | High — requires explicit logic in application code to handle invalidation correctly |
| Database Cache | Database engine internals | Query plans, frequently accessed rows | Managed automatically by the database engine, though tuning matters |
The Cost Equation Nobody Talks About
Infrastructure teams at companies running workloads on platforms like Amazon Web Services’ cloud infrastructure understand this intuitively: every cache miss is a trip back to the origin, and every trip costs compute cycles, network bandwidth, and latency. At scale, those costs compound fast.
A single percentage-point improvement in cache hit ratio across a high-traffic platform can eliminate thousands of dollars in monthly compute spend. And that’s before factoring in the user experience gains. Faster pages convert better. This isn’t speculation; Google’s own research has repeatedly linked page load time to bounce rates and conversion metrics.
Still, over-caching carries its own risks. Serving stale pricing data on an e-commerce platform, for instance, can trigger customer disputes or, worse, regulatory scrutiny in markets with strict consumer protection rules.
Cache Invalidation: The Hardest Problem
There’s a well-worn joke in computer science: the two hardest problems are naming things, cache invalidation, and off-by-one errors. The humor lands because cache invalidation genuinely is difficult.
Deciding when to expire or purge cached data requires balancing freshness against performance. Time-based expiration (TTL) is the simplest approach, but it’s blunt. Event-driven invalidation, where the cache is cleared when the underlying data changes, is more precise but architecturally demanding. Most production systems use a hybrid, and most production systems still get it wrong occasionally.
Reframing Cache Strategy Through Decision Architecture
Applying principles from decision science and neuro-linguistic programming offers an underappreciated lens on caching strategy. NLP emphasizes that the map is not the territory. In caching terms, the cached copy is not the source of truth. Recognizing this distinction at an organizational level changes how teams approach cache design.
When engineers anchor too heavily on the cached representation, they risk building systems that treat convenience as accuracy. Reframing the internal dialogue around caching, from “we have the data” to “we have a snapshot of the data, and here’s our confidence in its freshness,” introduces a healthier skepticism that improves system reliability. This kind of meta-awareness, borrowed from cognitive frameworks, encourages teams to ask better questions before writing a single line of cache logic.
Outcome-oriented thinking, another NLP pillar, suggests defining the desired state before selecting the mechanism. Rather than defaulting to “cache everything,” teams that start with “what latency does this user flow require, and what staleness is acceptable?” tend to build leaner, more resilient architectures. The framing effect matters: presenting caching as a risk-management decision rather than a pure performance optimization shifts the conversation toward durability and correctness.
Rapport-building within cross-functional teams also plays a role. When product managers understand why a cache TTL was set to five minutes instead of thirty seconds, they make better tradeoff decisions downstream. Shared mental models reduce friction. And in organizations where engineering and business teams speak different languages about the same infrastructure, that alignment is arguably the highest-leverage improvement available.
Frequently Asked Questions
What is a cache hit versus a cache miss?
A cache hit occurs when the requested data is found in the cache and served directly, avoiding a trip to the origin. A cache miss means the data isn’t present, forcing the system to retrieve it from the primary source and, typically, store it in the cache for next time.
Does caching affect SEO?
Yes. Page speed is a ranking factor for search engines, and proper browser and CDN caching directly improves load times. Sites that fail to leverage caching effectively often score poorly on Core Web Vitals, which Google uses as part of its ranking signals.
How do I know if my cache configuration is working?
Monitor your cache hit ratio. A ratio above 90% generally indicates healthy caching for most web applications. Below that, investigate whether TTLs are too short, whether cache keys are too granular, or whether invalidation is happening too aggressively.
Is Redis the only option for application-level caching?
Not at all. Memcached remains widely used for simpler key-value caching needs. Some applications use in-process caches like Caffeine for Java or lru-cache for Node.js. The right choice depends on data structure complexity, persistence requirements, and operational overhead tolerance.