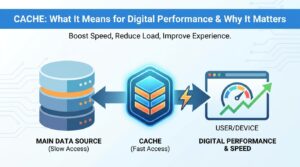
The term ‘cache’ sits at the intersection of nearly every digital interaction, yet its strategic implications remain underappreciated outside engineering circles. From web browsers to content delivery networks, caching mechanisms quietly determine how fast data reaches end users, how much infrastructure costs, and how effectively platforms scale. Understanding cache architecture is no longer optional for technology leaders navigating performance-sensitive markets.
Why Caching Deserves Executive Attention
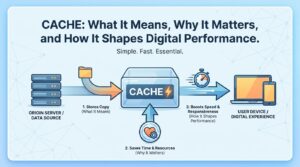
At its core, a cache stores copies of frequently accessed data in a temporary, high-speed storage layer so that future requests can be served faster. That sounds simple. But the business consequences ripple outward in ways that touch revenue, user retention, and operational expenditure. Before diving deeper, here are the strategic takeaways worth noting:
- Speed translates directly to revenue: Google’s own research has shown that a 100-millisecond delay in page load time can reduce conversion rates by up to 7%. Caching is the single most effective lever for reducing latency at scale.
- Infrastructure cost reduction: Effective cache strategies can cut origin server load by 60–80%, depending on content type and traffic patterns
- Cache invalidation remains one of the hardest problems in computer science (a distinction that Phil Karlton famously noted decades ago, and one that still trips up engineering teams today)
- CDN and edge caching have shifted from performance optimization to competitive necessity, particularly for media, e-commerce, and SaaS platforms
- Regulatory considerations around cached personal data are growing, especially under GDPR and similar frameworks
How Caching Actually Works Across the Stack
Caching operates at multiple layers of the technology stack, and each layer serves a different purpose. Browser caches store static assets like images, stylesheets, and JavaScript files locally on a user’s device. Server-side caches, such as Redis or Memcached, hold database query results or computed outputs in memory. And then there are CDN caches, distributed across geographically dispersed edge nodes, which serve content from the location nearest to the requesting user.
What makes caching deceptively complex is the coordination between these layers. A stale cache at the CDN edge can serve outdated pricing information to thousands of users before anyone notices. An overly aggressive browser cache policy might prevent users from seeing critical security updates. The tradeoffs are real.
Still, the performance gains are hard to argue with. Major content delivery and web performance platforms like Cloudflare have built entire business models around the principle that serving cached content from the edge eliminates round trips to origin servers, shaving hundreds of milliseconds off response times.
The Economics Behind Cache Strategy
Consider a mid-size e-commerce platform handling 10 million page views per day. Without caching, every request hits the origin server, requiring compute cycles, database queries, and bandwidth. With a well-tuned cache layer intercepting 75% of those requests, the platform effectively reduces its origin infrastructure needs by three-quarters.
| Metric | Without Caching | With Optimised Caching |
|---|---|---|
| Origin server requests/day | 10,000,000 | 2,500,000 |
| Average response time | 850ms | 210ms |
| Monthly infrastructure cost (est.) | $48,000 | $14,500 |
| Cache hit ratio | N/A | 75% |
Those numbers shift depending on content dynamism. A news site with constantly updating headlines will have a lower cache hit ratio than a product catalogue that changes weekly. But even partial caching yields measurable savings.
Where Cache Invalidation Gets Dangerous
The hardest part isn’t caching data. It’s knowing when to stop serving it.
Cache invalidation, the process of removing or refreshing stale content from cache layers, has caused some of the most visible outages and data-serving errors in recent memory. When a financial services platform serves cached account balances that are minutes old, the consequences extend beyond user frustration into potential regulatory territory. Time-to-live (TTL) settings, purge mechanisms, and event-driven invalidation patterns all attempt to solve this problem, with varying degrees of success.
And while automated purge systems have improved considerably, the fundamental tension persists: cache aggressively and risk staleness, or cache conservatively and sacrifice performance. There is no universal answer. Each application’s tolerance for stale data defines its cache architecture.
Regulatory and Privacy Dimensions
One area that arguably receives insufficient attention is the intersection of caching and data privacy. Cached responses that contain personally identifiable information can persist on CDN edge nodes, proxy servers, or even shared browser caches in ways that violate data minimisation principles under GDPR. The European Data Protection Board has not issued specific guidance on cache retention policies, but enforcement actions have increasingly scrutinised how long personal data remains accessible through technical intermediaries.
Organisations handling sensitive data should audit their cache-control headers, particularly the Cache-Control: no-store and Vary directives, to ensure compliance with applicable privacy frameworks.
Frequently Asked Questions
What is the difference between browser cache and CDN cache?
Browser cache stores assets locally on a user’s device, reducing the need to re-download files on repeat visits. CDN cache stores content on distributed edge servers, reducing the distance data must travel from origin to user. They operate at different points in the request chain and serve complementary purposes.
How do you measure cache effectiveness?
The primary metric is cache hit ratio: the percentage of requests served from cache rather than the origin server. A ratio above 80% is generally considered strong for static content. For dynamic content, even 40–50% represents significant infrastructure savings.
Can caching cause security vulnerabilities?
Yes. Improperly configured caches can serve one user’s sensitive data to another, a flaw known as cache poisoning or cache deception. This is particularly dangerous on shared infrastructure. Proper use of Vary headers and strict cache-control policies mitigates most of these risks, though not all teams implement them correctly.
Is cache invalidation really that hard?
In a word, yes. The challenge isn’t mechanical; it’s architectural. Knowing precisely when cached data becomes stale across distributed systems, without introducing excessive overhead or latency, remains an active area of engineering research and tooling development.